Four Failure Shapes From Public Postmortems
Seven published incidents, two predating LLMs, collapse into four shapes: the label became the goal, the gate never held, validation stayed inside, and the recovery was never tested.
Tag
8 posts
Seven published incidents, two predating LLMs, collapse into four shapes: the label became the goal, the gate never held, validation stayed inside, and the recovery was never tested.
AI can do more than I let it do. A practitioner's boundary list — the places I deliberately don't use it, the two questions that draw the line, and where I have already changed my mind.
A 200 OK tells you nothing when the failure is a plausible wrong answer. Instrumenting agent systems: the span model, payload policy, tail sampling, cost accounting, and the path to diagnosis.
Hallucination is a family of failures, not one bug. A mitigation playbook: coverage versus utilization, grounding by construction, detection that routes, and containment.
Quality is not a number. A production framework for measuring AI systems: component metrics, calibrated judges, statistical honesty, and the failure modes of measurement itself.
Permissions, output validation, multi-agent delegation, and the audit trail that reconstructs the decision chain. A production handbook for shipping agents that survive contact with reality.
An LLM agent is a commitment, not a category. Here's the decision framework, the failure modes, the three-layer reliability model, and the hybrid architecture that actually works in production.
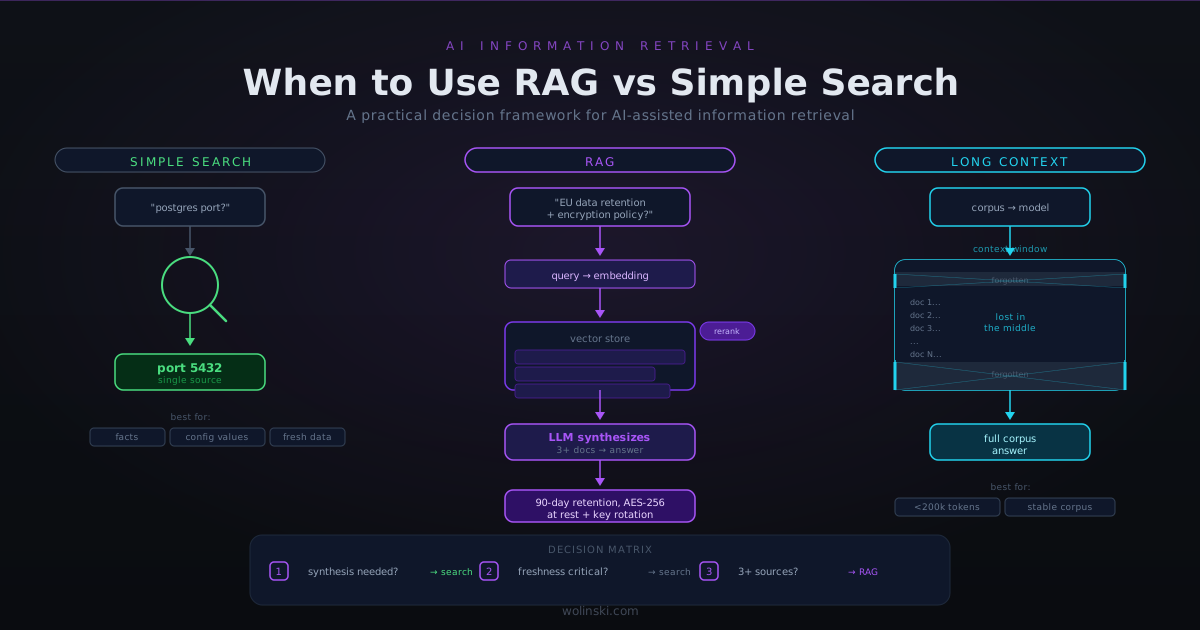
RAG sounds impressive, but most questions don't need synthesized answers from multiple documents. Here's how to choose the right approach.